Wikipedia Calls for Tighter Controls on AI Agents |
Unauthorised edits and heavy automated traffic have raised concerns about how to protect the free websites people rely on. |
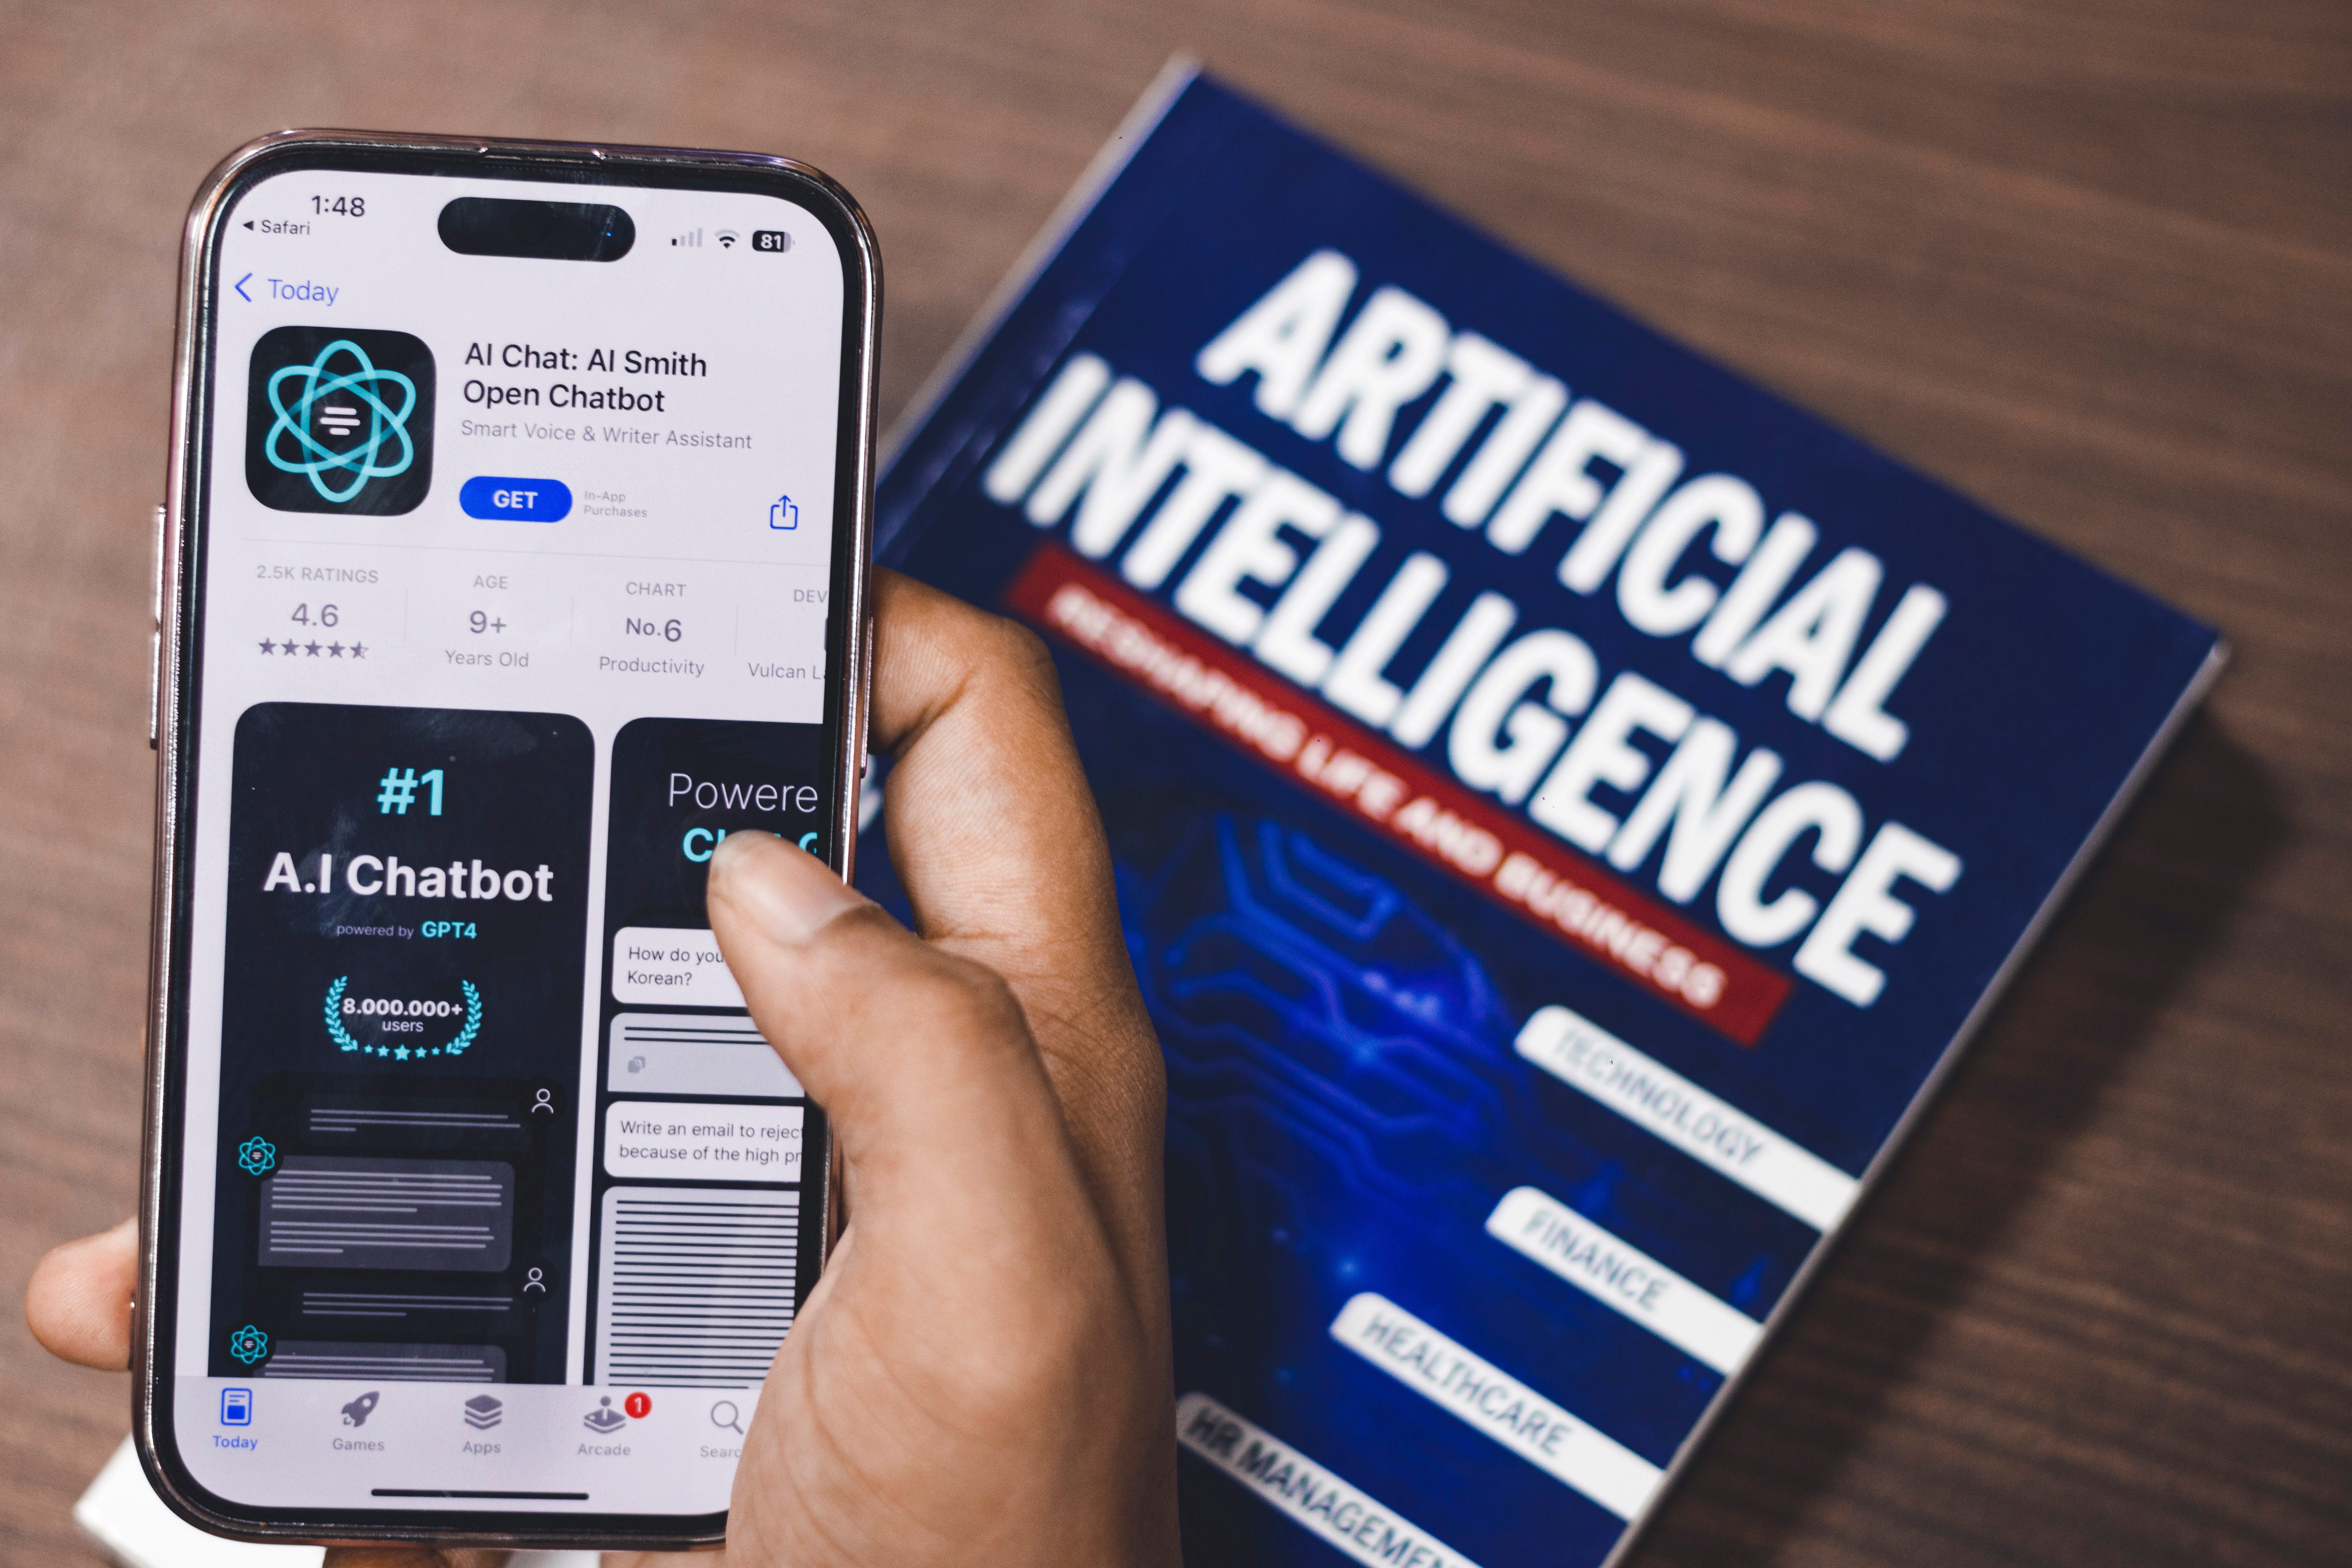
When an AI tool gathers information online, someone else’s website has to handle the visit. Multiply that activity millions of times, and the pressure can become substantial.
The Wikimedia Foundation, which hosts Wikipedia, says it discovered unauthorised activity it believes came from OpenAI-operated AI agents. Its findings, published on 5 October, include unapproved edits, attempts to misuse online tools and large volumes of automated requests.
What is an AI agent?
An AI agent is software that can take steps toward a task, such as visiting websites and collecting information, without a person directing every click.
That ability makes its limits important: permission to read information should not automatically mean permission to change a website or use its tools.
What Wikimedia found
The foundation identified three types of activity:
None of the identified edits appeared on pages visible to general readers. Wikimedia found no evidence that its systems or data were compromised or that its platforms were used for agents to coordinate with one another.
The pressure on everyday websites
Wikimedia says excessive traffic may have contributed to a partial data-service outage in May, although that connection remains unconfirmed.
Its concern extends to the people maintaining these resources: unwanted activity takes time to investigate and can make services harder for ordinary visitors to access. It wants developers to make agents identifiable and give website operators control over their access.
For someone looking up information for school, work or personal interest, the issue is continued access to dependable resources. This report does not establish that readers’ personal information was stolen or that the articles they read were altered.
OpenAI’s response
OpenAI told The Verge it was working with Wikimedia to review the findings and would share relevant information as its investigation progressed. It said it had not verified whether its bots contributed to the May outage.
The Bottom Line
AI tools depend on websites that people build and maintain. Keeping those resources available means developers must take responsibility for how their agents behave, including respecting the boundaries set by website owners. |
More from Joburg Insider
Nov 3, 2026
One Binder, Clear Steps, Useful Information
One binder, clear sections and a few essential pages can help your family find important information when you cannot guide them.
Nov 3, 2026
Prepare Before Bringing a Pet Home
A home inspection, permission to keep pets and introductions to existing animals form part of finding the right match.
Nov 2, 2026
A Chance to Earn the Green and Gold
Two Bulls players are among the uncapped selections in Rassie Erasmus’s squad for November’s Nations Championship Tests.
Nov 2, 2026
Find Your Place in Local Community Action
Find practical ways to support your Johannesburg neighbourhood through residents’ associations, organised community action and better municipal fault reporting.
0 Comments
Join the conversation
Be the first to comment
Share your thoughts above.